The business question
Can reimbursement context help healthcare-software sales analysts prepare more relevant account-discovery questions? SpecialtyPulse is an independent prototype exploring that hypothesis for teams selling EHR, practice management and revenue cycle software.
The proposed workflow brings payment comparisons, account context and open questions into a review brief. Reimbursement patterns provide starting points for investigation. Account needs require confirmation through discovery before recommending software. Intended users have not confirmed this workflow or evaluated whether reimbursement context improves their discovery questions.
All data is synthetic. The 2023 base uses a CMS-style schema; 2021–2022 are generated comparison scenarios. Payment signals describe the practice side, while pipeline dollars represent hypothetical software contracts. Account discovery is still needed before a software recommendation or outreach decision.
Delivered work
The delivered prototype connects a Databricks pipeline, an Airflow-checked export and a React review workflow. It processes 29,982 synthetic records into 870 reporting rows and carries source references into downloadable briefs.
Three decisions shape the workflow: service-weighted payments and specialty/year provider counts support reproducible comparisons; pipeline cleanup stays separate from discovery; and the project-defined pressure index remains an optional experiment.
The brief carries procedure evidence, notes, source references and an optional sales appendix. A separate CSV contains the complete specialty overdue roster regardless of pagination. Missing sales coverage stays unavailable. Drafts last until reload, completeness checks field presence, and downloads save without sending or assigning work.
One review, from signal to next check
For Dermatology / HCPCS 99213, the generated 2022 scenario has $108.05 per service across 3,626 services. The synthetic 2023 base has $104.91 across 3,777 services: payment falls $3.14 (2.9%), while service count rises 151 (4.2%).
An illustrative brief records that change, asks which source rows and service mix explain it, and requests a calculation check from the analyst. Its optional pipeline context shows 53 open opportunities totaling $4,579,800 in assumed USD annual contract value (ACV). At the constructed March 31, 2026 snapshot, 25 are overdue, totaling $2,121,500, while 28 are not yet overdue. Sales operations must reconcile stages and close dates before pipeline planning. These amounts are unweighted exposure, not recognized revenue or a forecast.
This is an illustrative assignment, with source and account validation pending. The main view presents payment changes, service counts and distinct providers. An optional experimental section documents the pressure-index formula and its validation limits.
Two fictional Dermatology account examples show why the same payment signal can lead to different next checks. The link opens the brief with Compare two fictional practices expanded. Each practice puts its decision, next reviewer and requested check before the supporting detail. Practice A's invented notes and work log describe duplicate billing-status entry and support a workflow review, with software fit pending. Practice B's invented notes and queue excerpt identify no billing-workflow need, so no software recommendation follows. Each includes a stakeholder, current systems, baseline, source excerpts and open questions. Either example can accompany the downloaded brief without replacing the analyst's notes.
The records precede the March 31, 2026 snapshot and are separate from the 500 sales opportunities. Differences between their invented baselines are not measured savings. They provide no human validation and were not part of the original AI comparison, which remains unchanged.
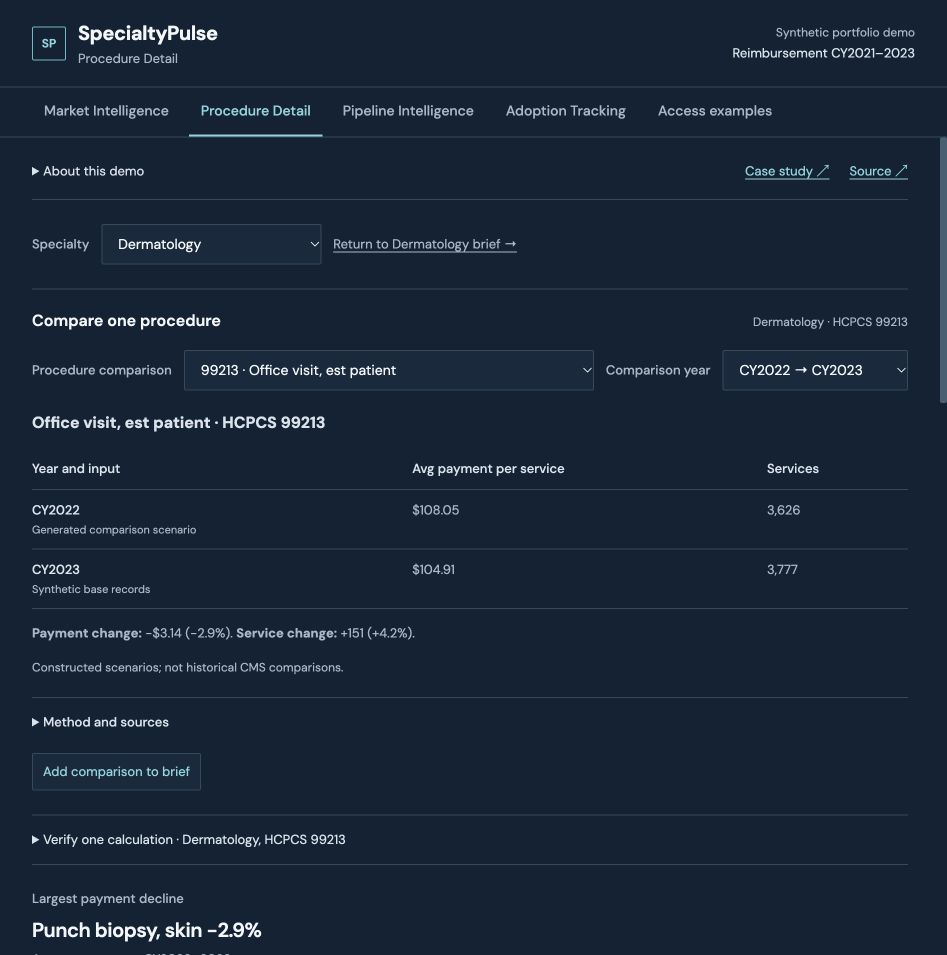
Captured October 26, 2026 after the UI cleanup. Both years are constructed comparison inputs.
What was verified
On October 26, Databricks Spark 4.2.0 processed 29,982 raw records into 870 reporting rows, matching every business value in the reconciled baseline. All four tasks in the clean Airflow 3.1.8 run passed on their first attempt. The public React dashboard uses that run's versioned export. Execution records document the run.
The displayed $104.91 reconciles to 57 raw rows, a weighted payment sum of $396,247.22 and 3,777 services. A simple row average would be $103.80. Spark counts distinct providers at specialty/year grain before procedure aggregation, so billing several procedures does not multiply the provider count. Independent Decimal checks cover all 870 groups; CI reruns the shared Spark transformations.
Airflow runs on a local Mac that must be awake and signed in with valid OAuth access. New exports require a separate website release. Public usage and access rules are illustrative; the demo serves the same synthetic data to everyone.
AI comparison: quality tied
On October 26, five fictional AI analysts and five separate AI reviewers completed ten briefs using constructed CSV reports and captured app drafts. Both methods produced 5 of 5 complete briefs, with 100 of 100 structured fields correct per method. Reviewers could state the next action for all ten briefs without clarification; no critical interpretation errors were found. No advantage for SpecialtyPulse was demonstrated.
This was an artifact simulation: agents did not navigate the browser, and timing excluded source gathering, coordinator preparation and reviewer work. Fresh contexts shared a model family, role-based workflows were assumed, and source cues prevented full method blinding. The test remains pinned to its original August 31, 2026 scenario and source revision d628a13, before the UI cleanup, recipient packet and March sales scenario. It was not rerun for these changes and cannot estimate human time savings.
Human validation remains 0 of 5 planned pairs. Usefulness, adoption and business outcomes are unmeasured. The comparison report and audit records include fictional role contexts, briefs, scoring and limitations. An earlier single-assistant rehearsal found and verified a missing sales-source link.
Next validation
First, observe how intended sales analysts prepare for account discovery. Then use five human analyst–reviewer pairs to compare questions prepared for comparable account scenarios with and without reimbursement context. Reviewers assess relevance to the account, support from the available evidence and usefulness of the requested next step, without being told the preparation method. Measure preparation time separately.
Metric definitions and sales scope
Payment grain. Raw payments are weighted by service count within specialty, HCPCS and year. Year comparisons use the previous year's denominator and displayed mart values rounded to cents. Missing inputs, duplicate matches or zero prior denominators leave changes unavailable. Specialty averages combine procedure-level measures; a payment below that blend is not evidence that a specific procedure is underpaid. Ratio outliers use the specialty/year distribution.
Provider grain. A provider counts once per specialty/year across procedures. An overlapping-procedure regression and independent raw-input reconciliation check every published specialty/year count.
Sales basis. Open-stage totals exclude Closed Won and Closed Lost and retain overdue opportunities. Closed-won ACV is a separate stage total. All 500 fixture opportunities are in scope, without a reporting-period filter; created dates span September 2, 2025–February 24, 2026 and close dates October 11, 2025–August 14, 2026. Dates and stages are constructed to be consistent with March 31, not captured or reconstructed CRM history. Closed-stage dates represent completion within the synthetic scenario; open-stage dates are expected. No opportunity is created after the snapshot, closed after the snapshot, or assigned a stage age longer than its existence. The build checks those relationships and the recorded fixture hash.
Overdue scope. At March 31, the 472 open deals total $40,178,200 in assumed ACV. Of these, 278 are overdue by 1–171 days ($23,546,900) and 194 are not yet overdue ($16,631,300). Only valid close dates strictly before that snapshot qualify; missing or invalid dates stay separate. Past-due dates alone do not close or remove deals. Owner ages use eligible overdue dates; an em dash means none. Sales records cover nine specialties, versus 29 in reimbursement reporting. No supplied specialty rows means unavailable coverage, not zero sales.
The scenario record pins the fixture hash and adjustment policy. The revision preserved IDs, amounts, stages and open-deal dates. It moved 12 future closed-stage dates before March 31 using their supplied stage ages, then aligned the other 16 closed-stage ages with their existing close dates. The historical AI study retains its original fixture, scenario and results.
The metric definitions, calculation trace and reproduction guide provide audit detail. Brief links pin raw inputs, reporting rows, sales records and run receipts to the build's repository revision.
Deployment evidence and operating limits
The stack is Databricks → Airflow-validated export → React. The earlier Domo integration was archived after trial access ended. The serverless job writes raw, staging and mart Delta tables using the same transformations as the local Spark/Parquet baseline. Airflow checks the receipt and export, saves an immutable versioned copy, and selects it for the next React build. The build rejects mismatched source, transformation or output hashes. Release checks also reject changed artifacts for a recorded run.
The first complete run exposed duplicate synthetic provider identifiers. These were corrected deterministically, with duplicate-key rejection retained before aggregation. Both the initial scheduled cloud refresh and a separate clean manual run completed; the public export comes from the clean run.
The local Mac's annual UTC schedule is enabled; its next run is due December 31, 2026 at 7 p.m. Eastern. Host availability and valid OAuth remain dependencies. The three Delta tables are replaced in individual commits, not one shared transaction. Operational use still requires real-source reconciliation, intended-user access enforcement, recovery tests and an alerting plan. The review list does not write to a CRM, and no actual sales review or CRM update has been recorded.
The selected run receipt and deployment runbook document execution and setup. Earlier Domo policy tests are archived and do not verify active access enforcement.
Proposed human comparison criteria
Confirm the workflow before testing. Alternate condition order across five human analyst–reviewer pairs and use comparable account scenarios with the same account facts; one condition adds reimbursement context. Each analyst prepares discovery questions, their rationale and a requested next check. Reviewers are not told the condition; record any remaining method cues.
Review both question sets against the same criteria:
- Account relevance: addresses a stated account goal, reported problem or important unanswered question.
- Evidence support: distinguishes provided facts from assumptions and avoids inferring account need solely from specialty signals.
- Useful next step: identifies a specific, justified question or check and the stakeholder or evidence needed.
For each pair and criterion, record whether reimbursement context helped, made no difference or hurt, with the reviewer's explanation and clarification requests. Record critical interpretation errors, including synthetic data treated as history or a blended average treated as a procedure-specific expected rate. Compare preparation time and data-gathering effort separately; agree acceptable effort with intended users before running the study.
These are planned criteria, not achieved human results. Use the paired findings to decide whether a larger trial is warranted. The earlier workflow and evaluation plan documents the app-versus-CSV proposal. The historical AI comparison remains unchanged.